Expert-built RL environments beyond software engineering
The work professionals are paid for, rebuilt as environments an agent can learn from. Each ships with a reference solution and a verifier we attacked before you did.
Domains
The agent works in the tools of the trade and delivers the files a professional would.
Electronics
PCB layout, failure cause analysisArchitecture
IFC construction models from drawing sheetsMotion design
Explainer videos, TV ad openings3D animation
Character rigging, skinning, animationGames
Playable Godot scenes with soundBiology
Binder design, binding kinetics triage
One task, start to finish
Character rig and animation, built with a technical artist.
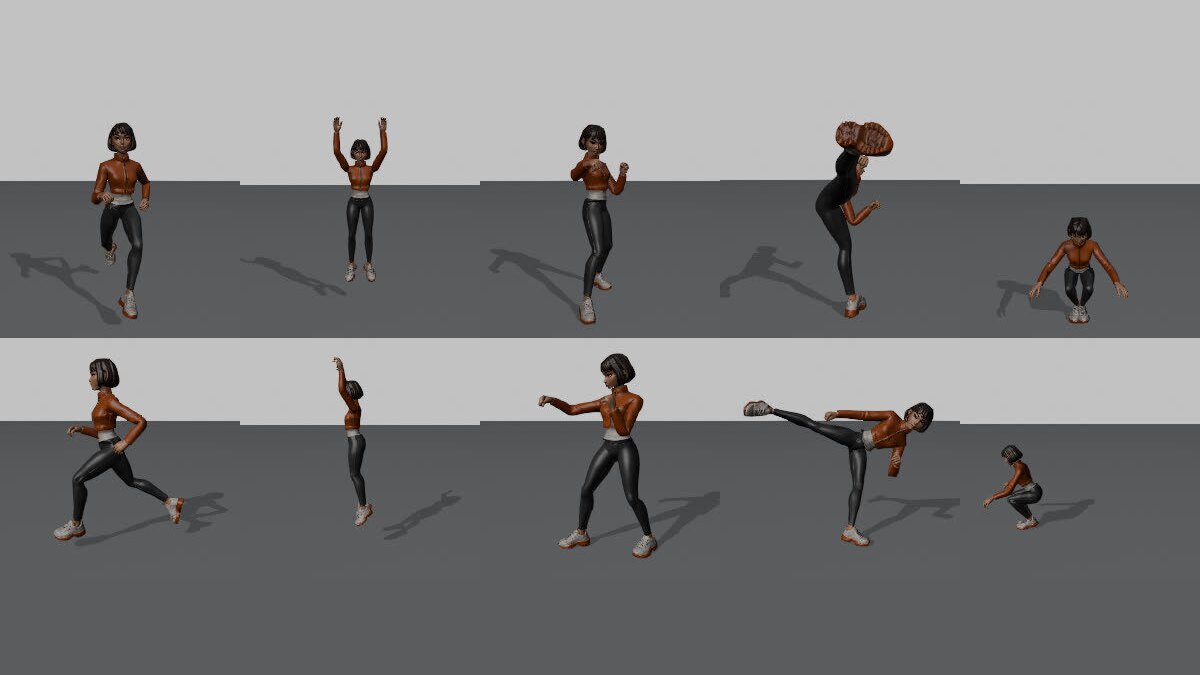
- Brief
- Rig and skin a game heroine, then animate five moves to match reference videos.
- The agent gets
- A character mesh and five reference videos.
- The agent delivers
- A rigged Blender file with five animation clips.
- Reward
-
- Rigged delivery
- Run
- Jump
- Punch combo
- Roundhouse kick
- Front flip
- Rig holds up
- Verifier checked
-
- 0.000empty work
- 1.000reference
- 9/9broken checks caught
- 7/7attacks blocked
- Models scored
-
- Claude Opus 5.50.99
- GPT-6.1 Sol0.95
- Muse Wonder 1.00.60
- Grok 4.70.57
- GPT-6 Luna0.37
How a task is built
A practising expert is in the first step and the last.
Author
An expert builds the task from real work and provides the reference solution.
Verify
We write the verifier in code and check it on known good and known bad work.
Attack
Agents try to earn reward without doing the work. Every hole they find gets closed.
Expert QA
The expert reads the model trials and confirms the verdicts match their judgment.
A reward you can train against
A verifier that can be gamed teaches a model to game it. So we try to break ours first, and ship the record of every attempt.
Fair
Empty work scores 0. Every correct solution passes, not only ours.
Stable
The reference passes on every repeated run.
Precise
Break one check of the reference and only that score drops.
Isolated
Scores come from code run on the delivered files, in a container without network.
Working with us
Start with the sample. Scale only after a pilot holds up on your own evals.
Sample
We send nine runnable tasks with every probe, attack and trial.
Call
We walk through the sample and what your model should get better at.
Pilot
A small batch in the domains you pick, built with practising experts.
Scale
Volume delivery in the domains that proved useful.
Request samples
All nine tasks, runnable, with reference solutions, verifiers and every trial.